
What you do not get is any way to tell which part of it is the legal text, which part is the regulator’s guidance, which part the model inferred, and which part is simply wrong.
Ask it to compare two regimes and it gets worse. “Compare” invites an assistant to find similarities, so it finds them — including where two regimes are built on genuinely different foundations.
The Regulatory Reporting Toolkit is built to make that failure structurally difficult rather than merely discouraged.
How it works
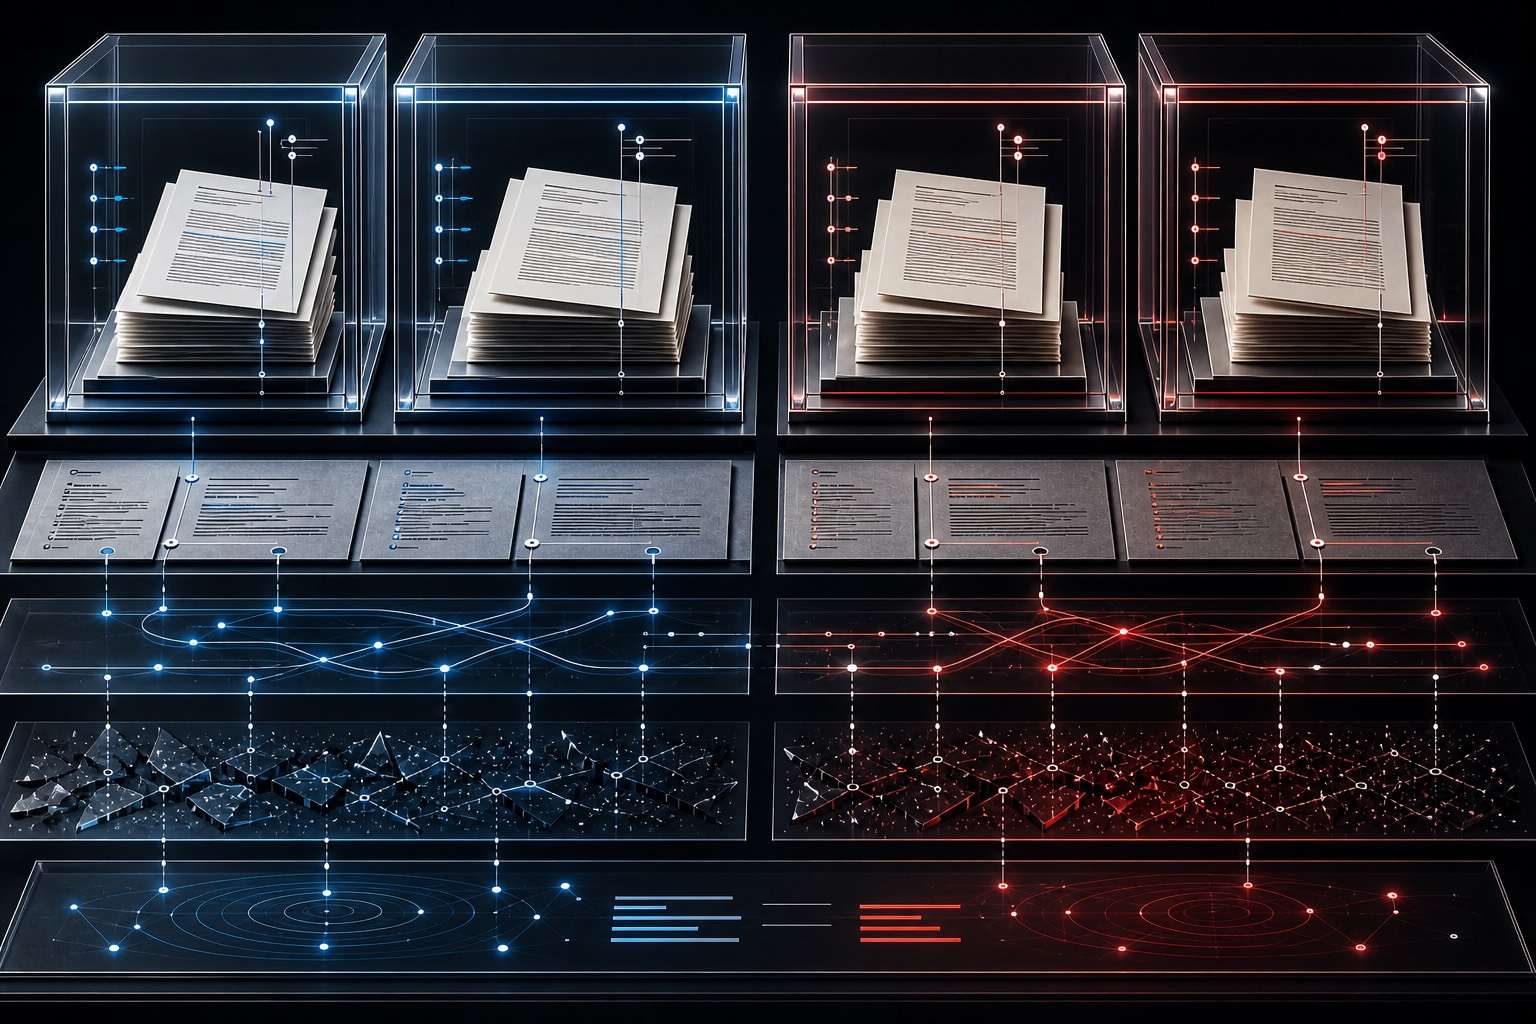
One specialist per regime, kept apart. Six subject matter experts each cover a single regulation and nothing else: Swiss transaction reporting and derivatives reporting under FMIA, EU derivatives reporting under EMIR, EU transaction reporting under MiFIR, and client classification under both MiFID II and FinSA. Each one works in its own isolated context. The EMIR expert cannot see the Swiss analysis, so it cannot quietly borrow from it.
Every statement names its source. A requirement cites the article and paragraph it comes from, and carries a tag saying how that citation was obtained — from a local copy of the official text, retrieved from an official website on a given date, or not verified at all. An unverified statement is labelled as one, so a reader can decide what to trust before relying on it.
Nothing loses its trail. Every finding gets a stable identifier, and every later statement names the finding behind it. A conclusion in the executive summary can be followed back to the specialist analysis and the article it rests on. Anything that cannot be traced that way is removed before delivery.
Disagreements survive. Where two regimes conflict, or where the evidence has a hole, that is recorded as a finding rather than tidied away. Both reach the final summary intact. The toolkit compares what each regime actually requires and refuses to declare two regimes equivalent — that determination belongs to a competent authority, not to software.
The run leaves an audit trail. Each analysis writes a dated set of files to disk that a reviewer can walk through months later, including which sources were used and on what date the answer was current.
What it is honest about
Its limits are part of the design, not a footnote.
It covers six Swiss and EU regimes. It does not cover FinIA, anti-money-laundering rules, SFTR, UK or US regimes, or anything else — and when a question falls outside its scope it says so rather than routing to the nearest-looking expert. Silence from it is not evidence that nothing else applies.
Everything it produces is decision support for a qualified professional to check, never advice, and never a final answer. It is least reliable exactly where questions get most specific: narrow fact patterns, novel structures, national implementing measures, and anything resting on supervisory practice rather than published text.
Who it is for
Compliance and regulatory reporting teams get a fast, structured first pass on a cross-border question, with every citation checkable and every gap visible — so the time goes into verifying a draft rather than assembling one.
RegTech and IT teams get a defensible input for building reporting systems: the requirements of each regime separated by jurisdiction, the differences between them named explicitly, and a traceable path from any statement back to the article behind it.
It is free, open source, and written in plain Markdown, so the method, the checklists and the templates can be lifted into your own process and adapted.
👉 See what is inside and how to get it ⭐ Go straight to the repository on GitHub